Speech recognition
Transcribe speeches in audio recordings to train speech recognition models to convert spoken language into written text or to interpret spoken commands.
Create high-quality and accurate audio annotations for top-performing models.
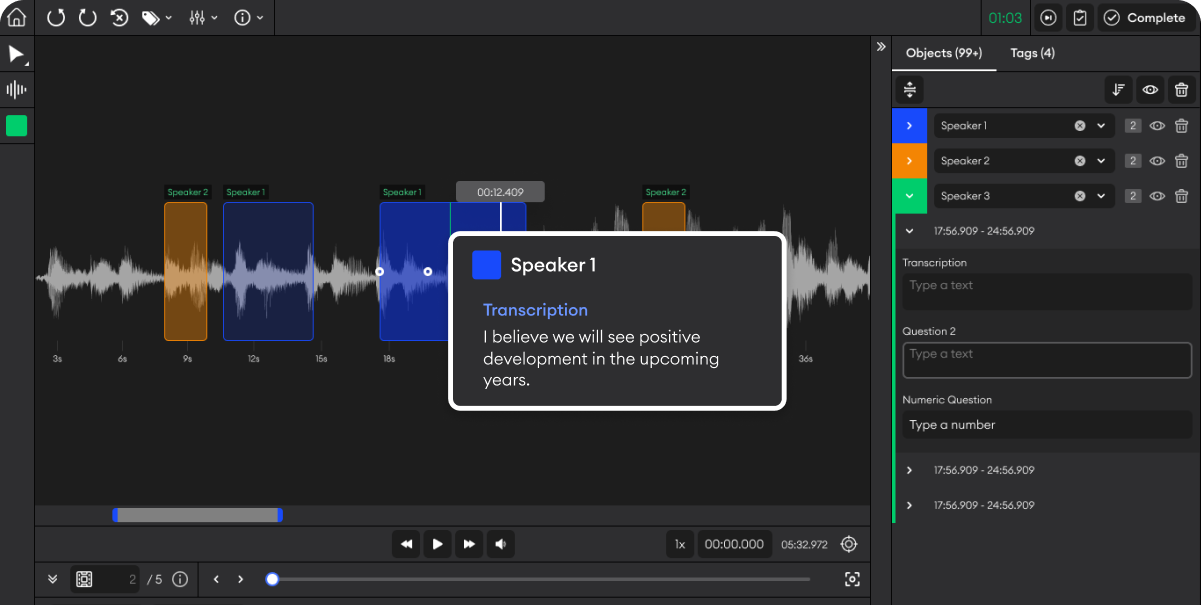
SuperAnnotate supports the most common audio types and file formats, making it possible to power all industries and use cases.
Transcribe speeches in audio recordings to train speech recognition models to convert spoken language into written text or to interpret spoken commands.
Annotate various features from an audio sample, such as rhythm and intonation, to train speaker recognition models that can identify voiceprints.
Identify and classify specific sounds within an audio recording, such as thunder or car honks, to train models to detect specific sounds.
Categorize your audios by assigning them with classes based on their contents and characteristics.
SuperAnnotate provides innovative solutions for a breadth of industries and use cases, from autonomous driving to robotics, and more.
Create top-quality training data across all data types.
Learn more: Annotation softwareAccess a global marketplace of 400+ vetted annotation service teams.
Learn more: Annotation servicesManage the performance of projects, annotators, and annotation QAs.
Learn more: Project and quality management